Grace Blackwell, desk-sized. One box, no cloud, your data.
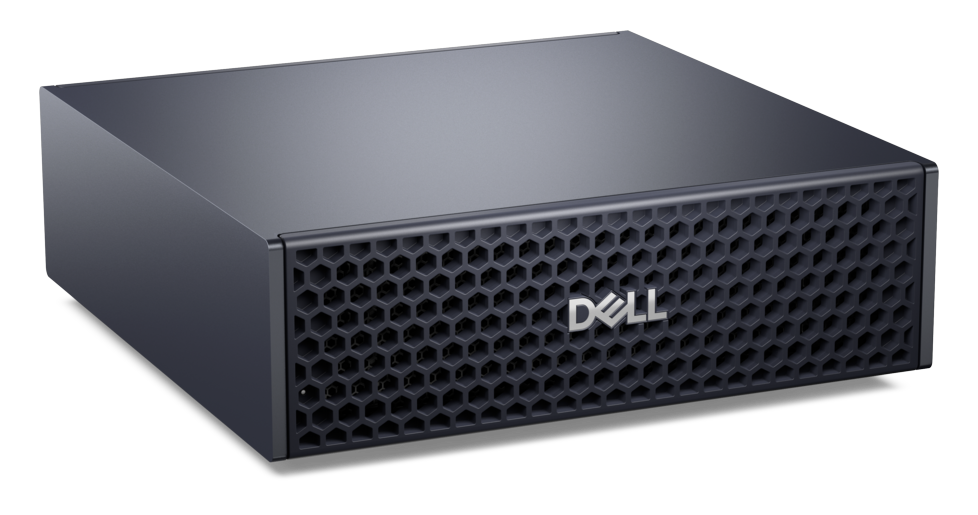
GB10 Grace Blackwell Superchip · 128 GB unified
What it runs: 70B-class models in FP4, up to 200B parameters; LoRA fine-tuning to ~13B; embeddings+rerank for RAG; vision and speech models. The whole stack, local.
Request quote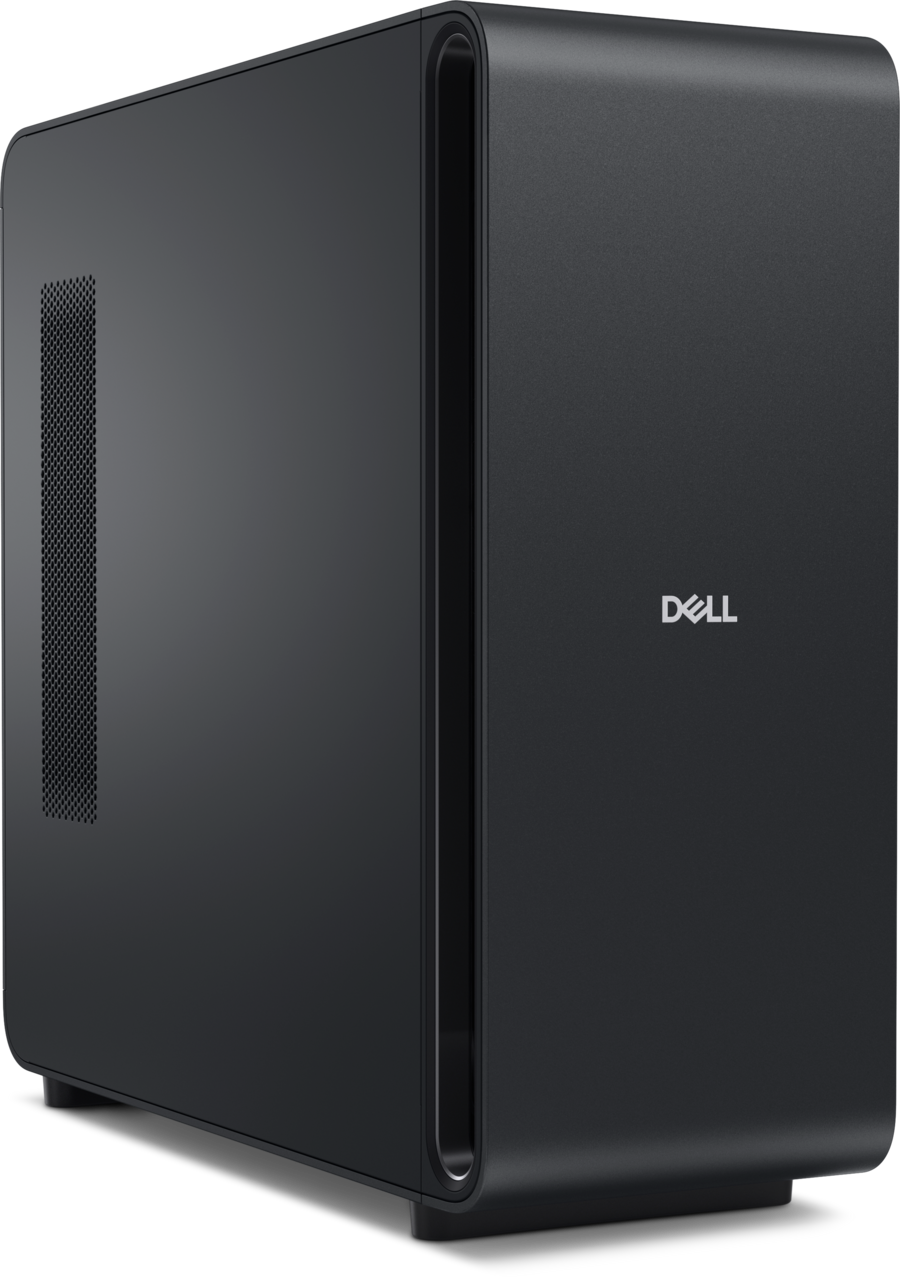
Blackwell Ultra · 496 GB-class memory
What it runs: 100B+ models at FP8/FP4, many simultaneous users, long-context retrieval, fine-tuning up the stack. The department inference server that happens to live under a desk.
Request quotePick one, or bring us a workload and we'll size it. These are starting points, not limits.
GB10 desktop · 128 GB unified
Local 70B-class inference, fine-tuning to ~8B, full dev stack. Replaces the GPU whispering in your closet. Need more later? A second GB10 over 200 GbE pools 256 GB — same silent desktop format.
Pro Max GB300 · Blackwell Ultra
One desktop for the whole team — 496 GB-class memory for 100B+ models, with headroom for long context and many simultaneous users.
PowerEdge R770 · 2× RTX PRO 6000 Blackwell
24/7 embeddings + retrieval for hundreds of users, redundant PSUs, in your server room.
PowerEdge XE7745 · up to 8 GPUs
The big node: 8 double-wide 600 W slots, air-cooled, quoted with networking and storage included.
Not sure which? Tell us the model and user count — we size it. A second GB10 over 200 GbE later pools 256 GB; the GB300 starts bigger. Configuring, testing and burn-in are available as an option.